Verified Policy RAG
Local LLM assistant for UK home insurance that checks every sentence before a customer sees it.
Outcome
0 / 39
Wrong answers reached a customer
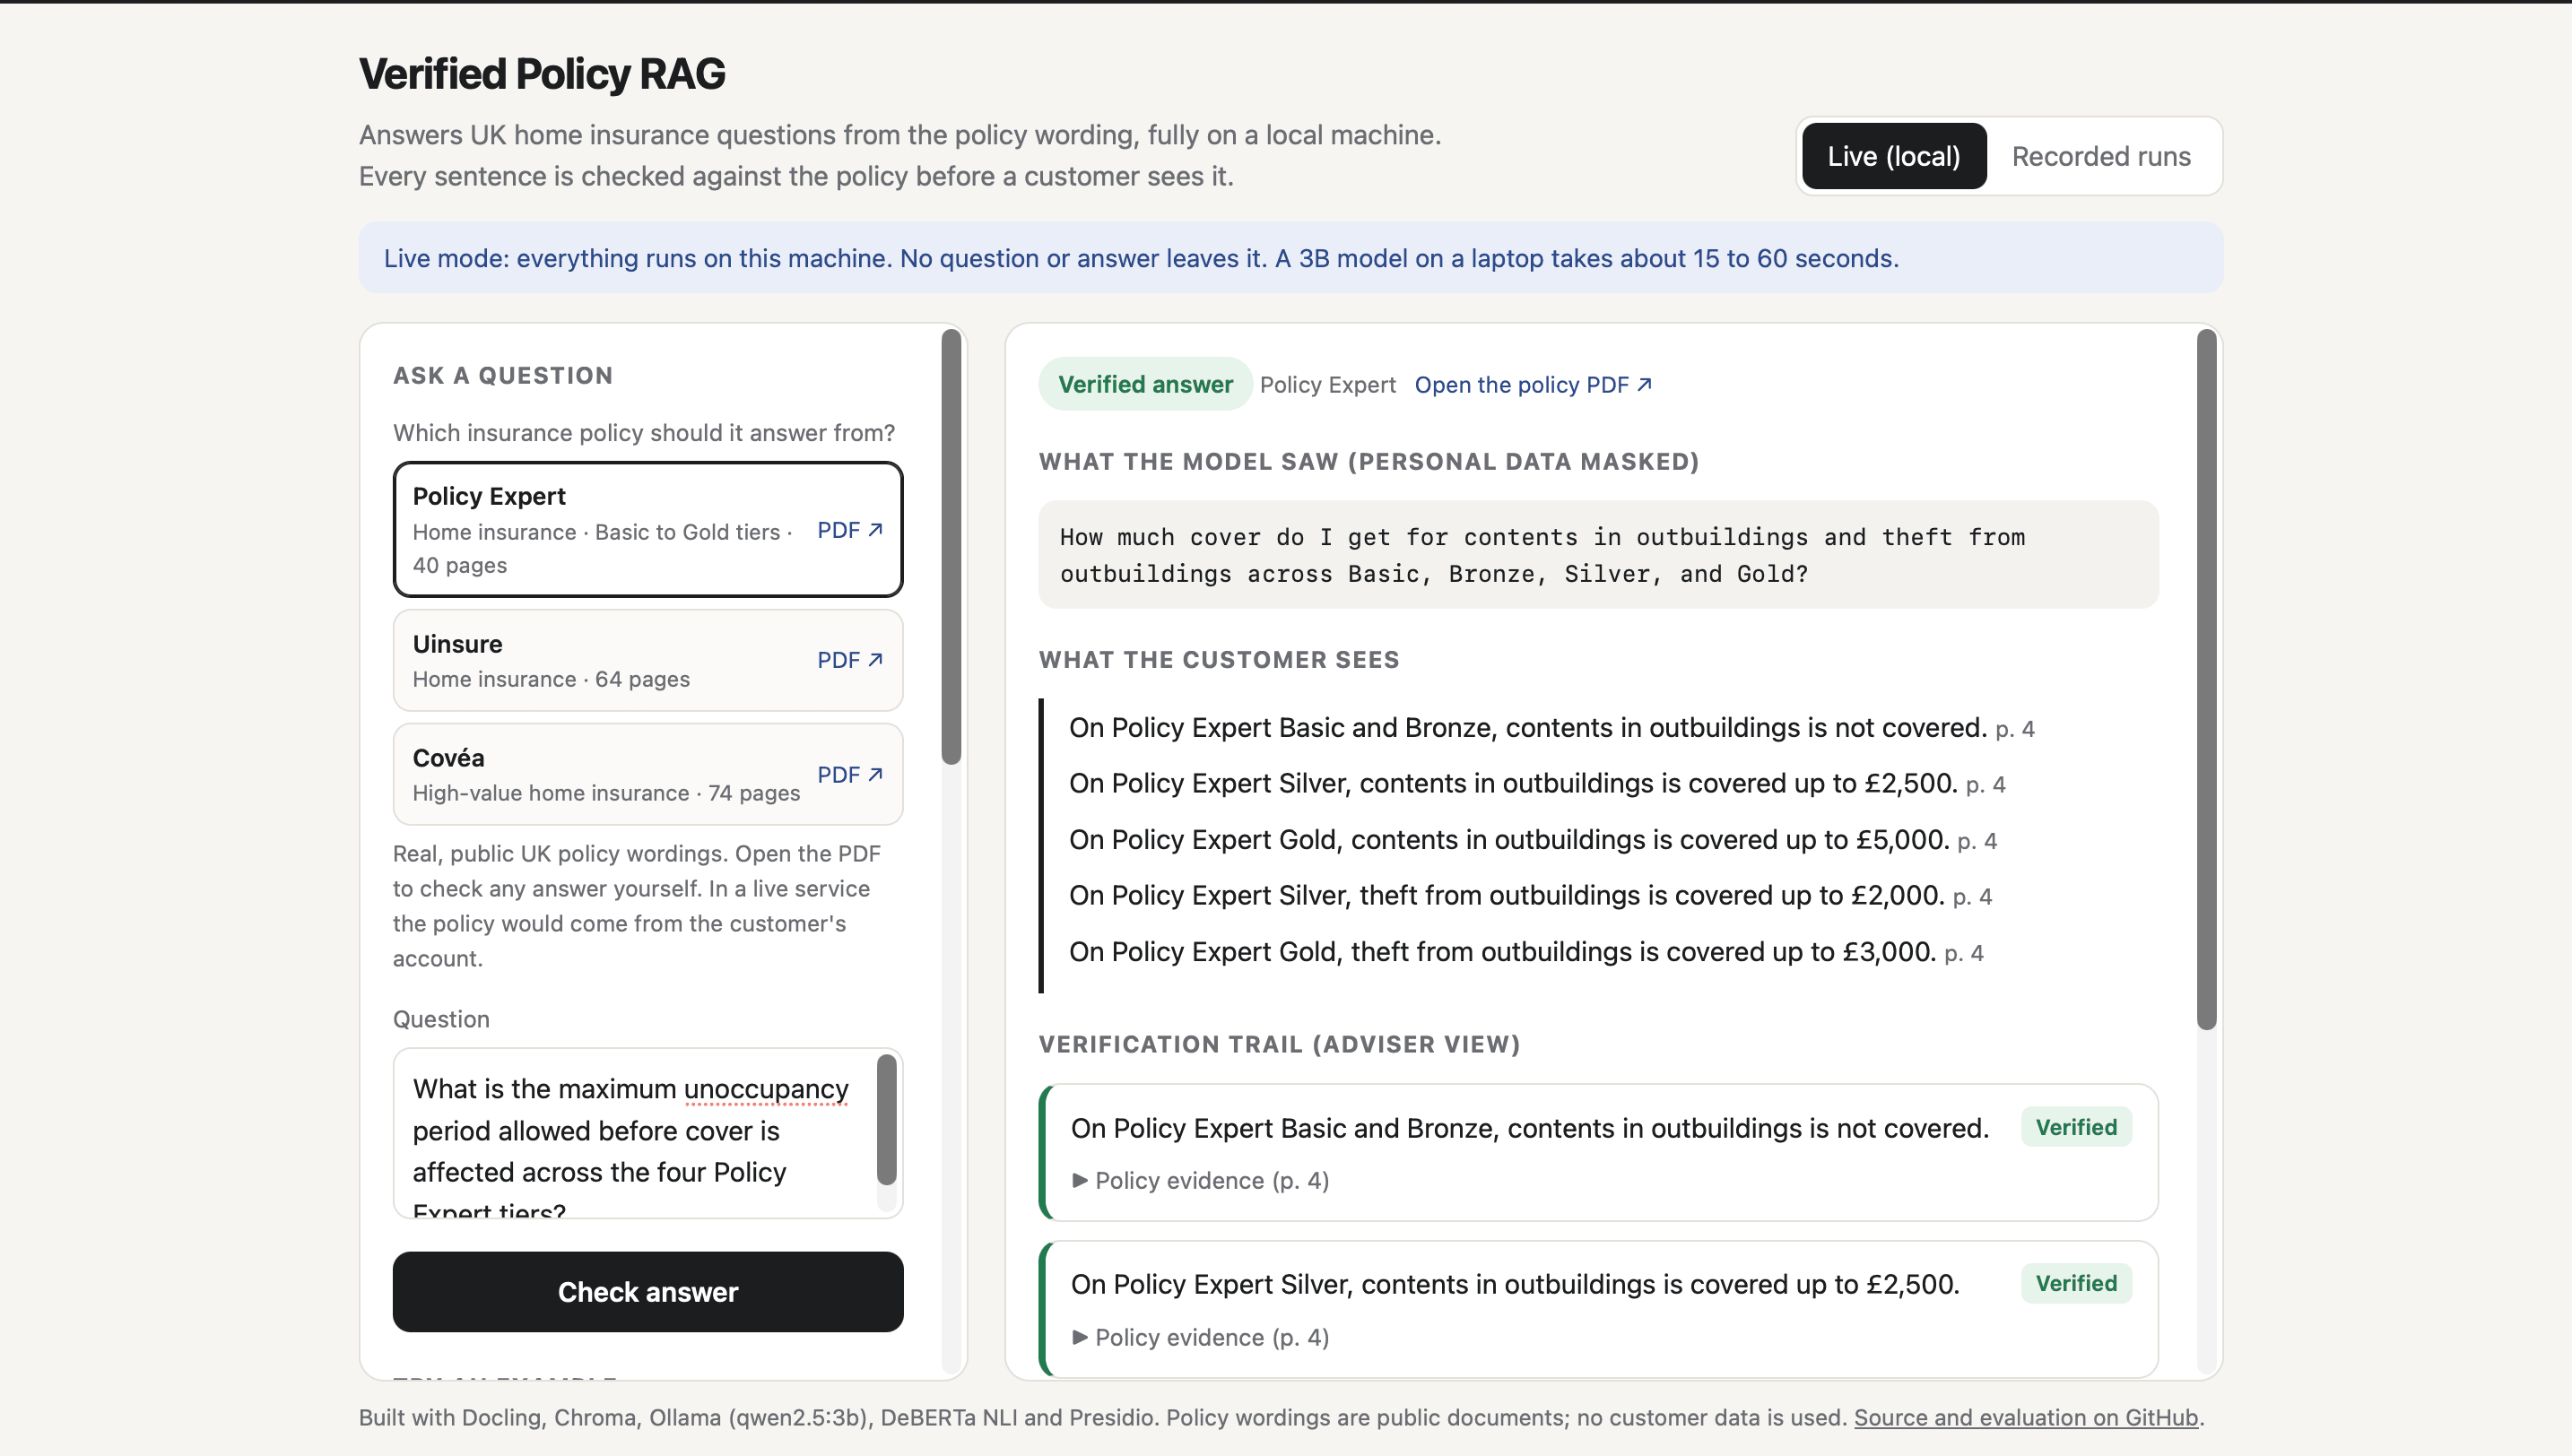
In the product
Overview
A fully local question answering system over three UK home insurance policy wordings (182 pages). It runs on an 8 GB laptop with no cloud APIs, so customer data never leaves the machine, and every sentence of every answer is checked against the policy before a customer can see it. Anything that fails a check is referred to a human adviser instead.
The problem
Insurers want to use language models on customer questions, but two things stop them. Customer data is sensitive, and sending it to models hosted abroad raises GDPR problems, so the model has to run on infrastructure the insurer controls. And a model that confidently tells a customer they are covered when they are not creates complaints and regulatory risk. The question I set out to answer: can a small model that runs locally be made safe enough that a wrong answer never reaches a customer, and can I prove it?
How it works
- 01Personal data (names, emails, UK phone numbers, postcodes) is masked before the question reaches the model or any log.
- 02Relevant clauses are retrieved from the customer's own policy, with a glossary that maps everyday words to policy terms.
- 03A local 3B model (qwen2.5:3b via Ollama) writes an answer with a citation for every sentence.
- 04Every sentence is checked: is it supported by the cited clause (DeBERTa NLI scored over short windows of the clause), is that clause actually about what the customer asked, does every figure match exactly, and does a policy exception apply to this customer's situation.
- 05If any sentence fails, the whole answer is withheld and the customer is referred to an adviser, with the reasons shown in an adviser view.
Architecture
Question
Customer input
Mask personal data
Presidio
Retrieve clauses
Chroma
Generate cited answer
qwen2.5:3b
Verify every sentence
4 checks
Verdict
3 outcomes
Verify every sentence
Verdict
Runs entirely on an 8 GB laptop. No cloud APIs.
Results
Evaluated on 39 questions, every expected answer checked by hand against the policy PDFs.
0 / 39
Wrong or misleading answers reached a customer
11 / 11
Bad model drafts caught on customer style questions
9 / 9
Out of scope questions referred to an adviser
0
Personal data leaks
94%
Retrieval recall, up from 74%
119
Automated tests guarding every fix
Trade-offs
The verification layer favours caution: when a sentence cannot be verified, the answer is routed to an adviser rather than shown. With the 3B model that fits on an 8 GB laptop, this produces a high referral rate on conversational customer questions. Because the checks are independent of the model, a larger model on server hardware would raise answer quality without changing the safety layer.
Reflection
The most valuable result came from evaluation design rather than modelling. Independent, customer style questions exposed failures that builder written tests had hidden, and they reshaped the retrieval design. The hardest failures were answers that were fully grounded yet wrong for the customer, which pushed the checks beyond citation matching towards relevance and policy exceptions. On constrained hardware, the leverage is in verification, not generation.